Claim
The keyed eval measured retrieval recall@8 at 18/24 (75.0%), the answer rate at 15/24 (62.5%), refusal of unanswerable questions at 6/6, and citation precision and faithfulness at 13/15 and 12/15.
Ask a hosted reader a question about a PDF corpus and get claims whose quotes are verbatim, highlighted on the page, with an inspectable retrieval trace and a calibrated refusal.
Live
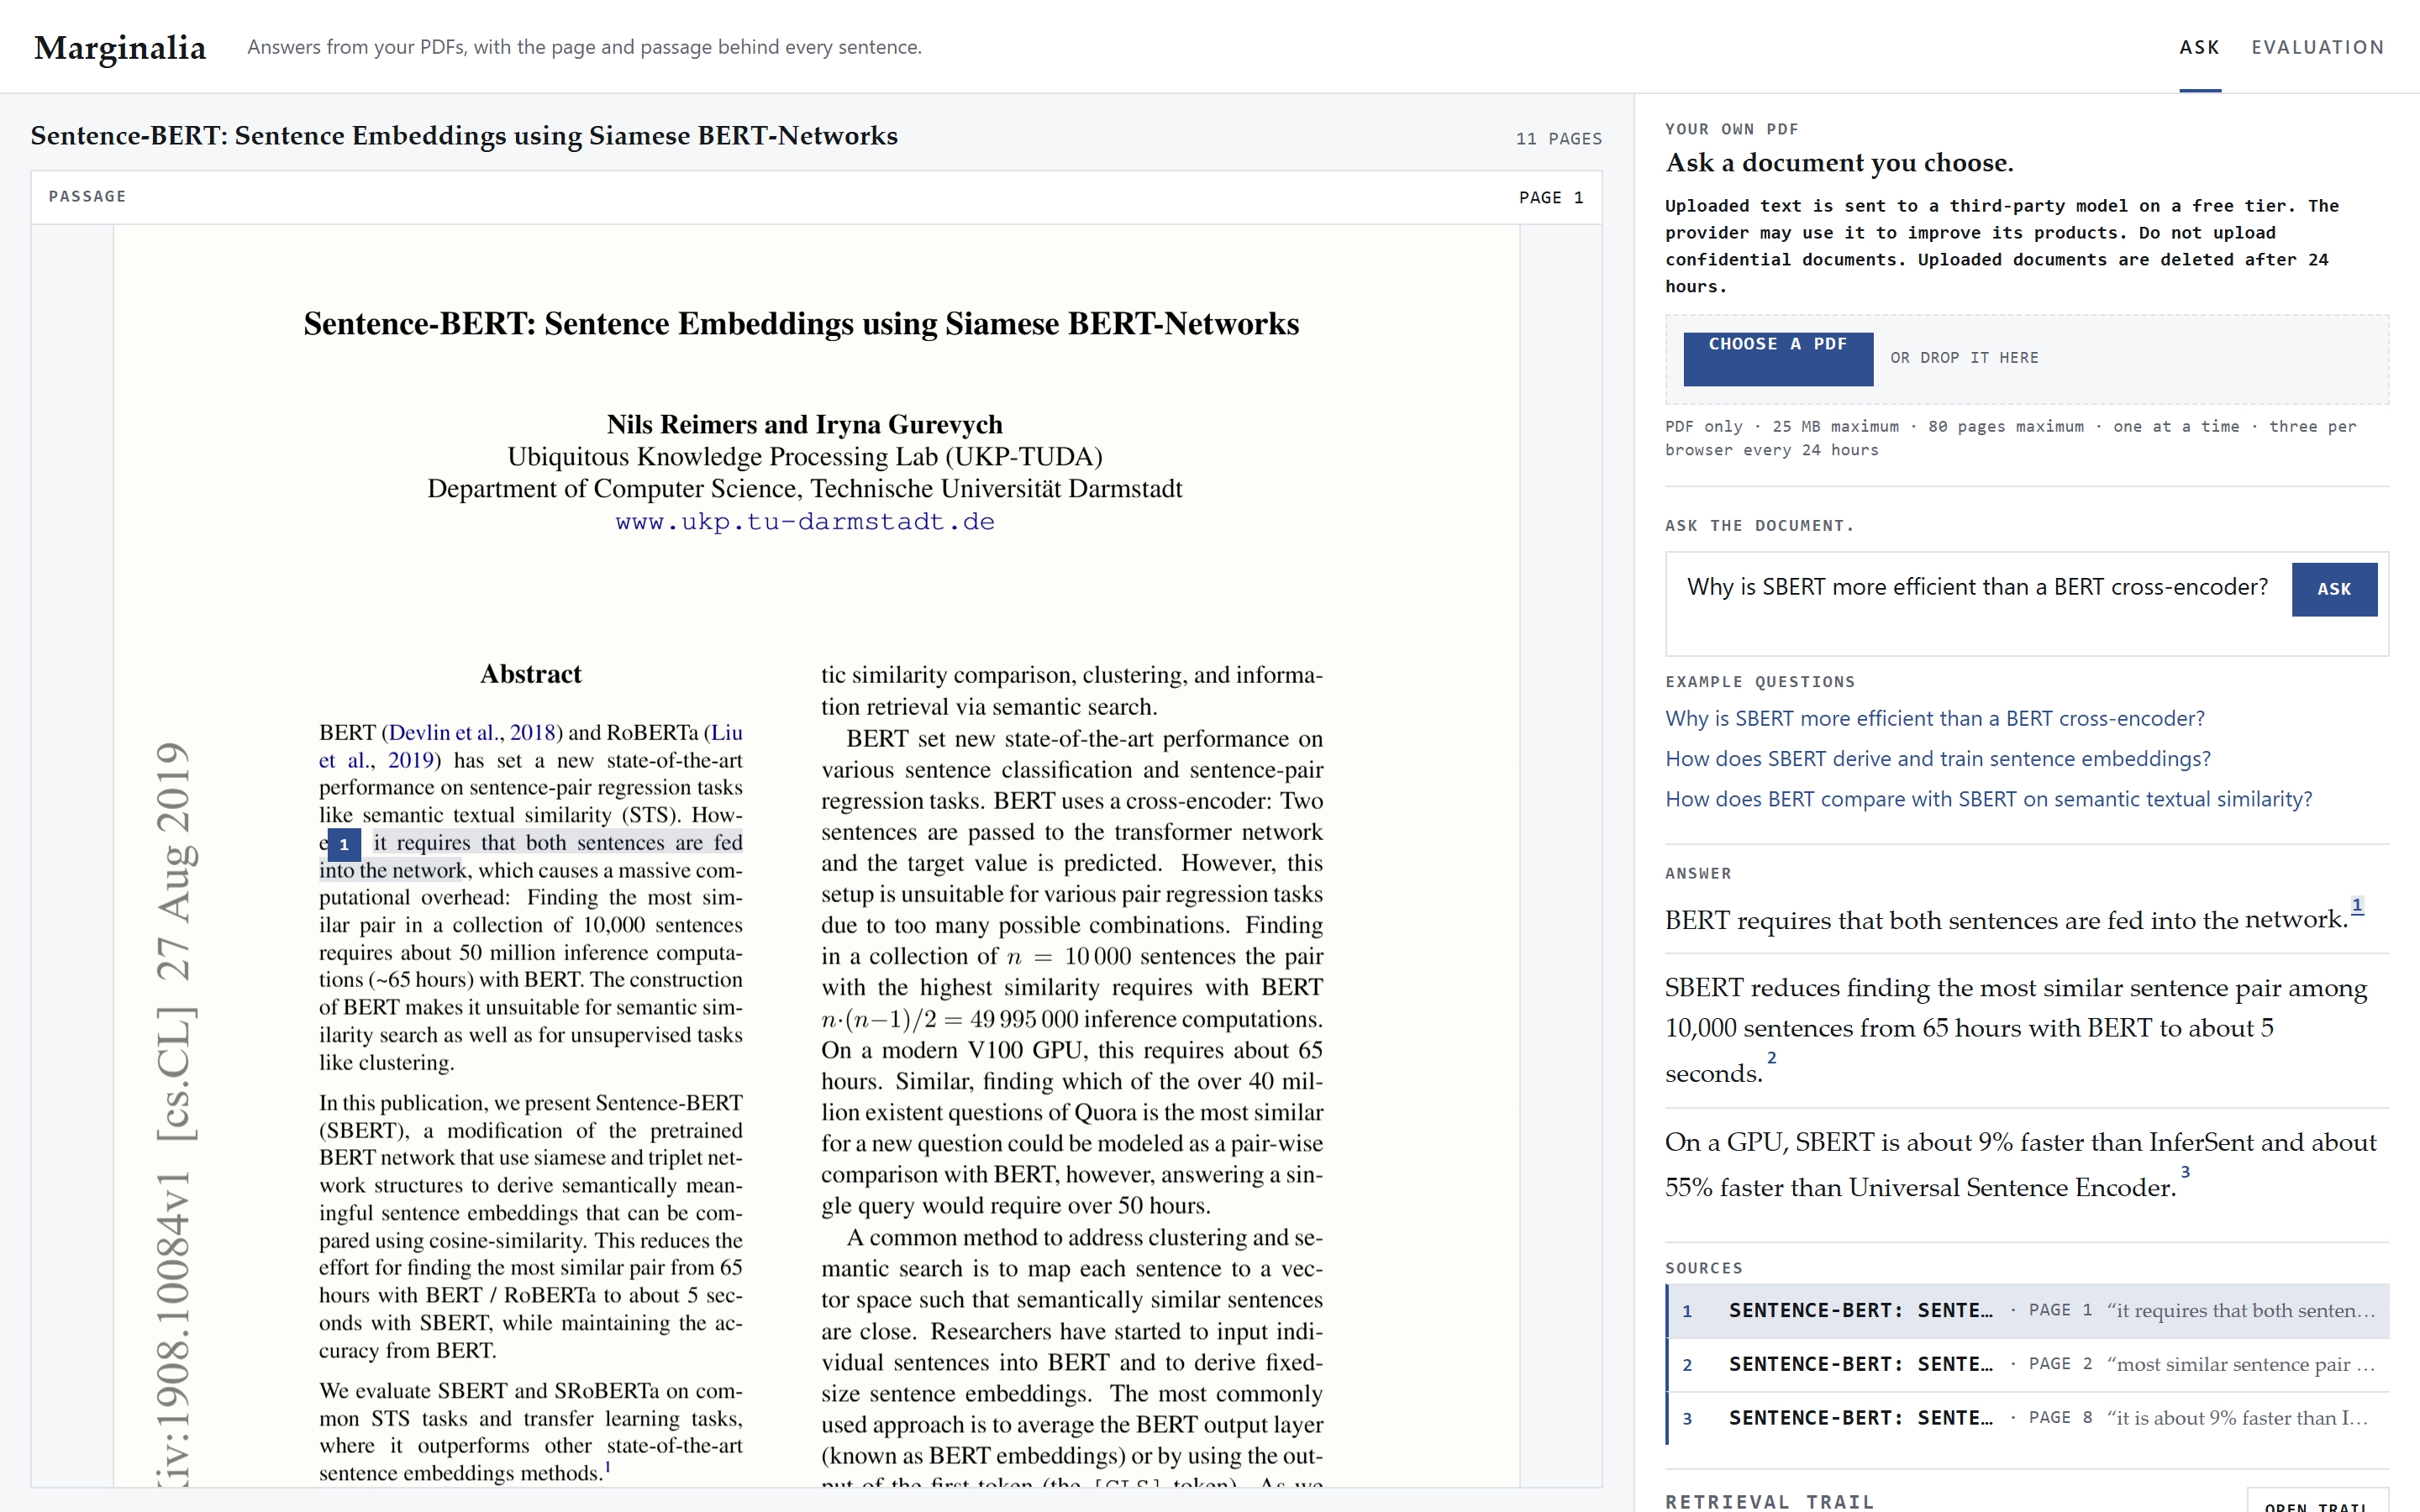
Ask the seeded Sentence-BERT paper why SBERT is more efficient than a BERT cross-encoder.
marginalia-ui.onrender.com marginalia-api-4pvl.onrender.com View the code
What to expect on the free instance
- The free instance sleeps after 15 minutes idle and takes about a minute to wake.
- The hosted corpus is five papers and 260 chunks; a question outside it is refused.
- A warm answer takes 17–25 s on the free instance.
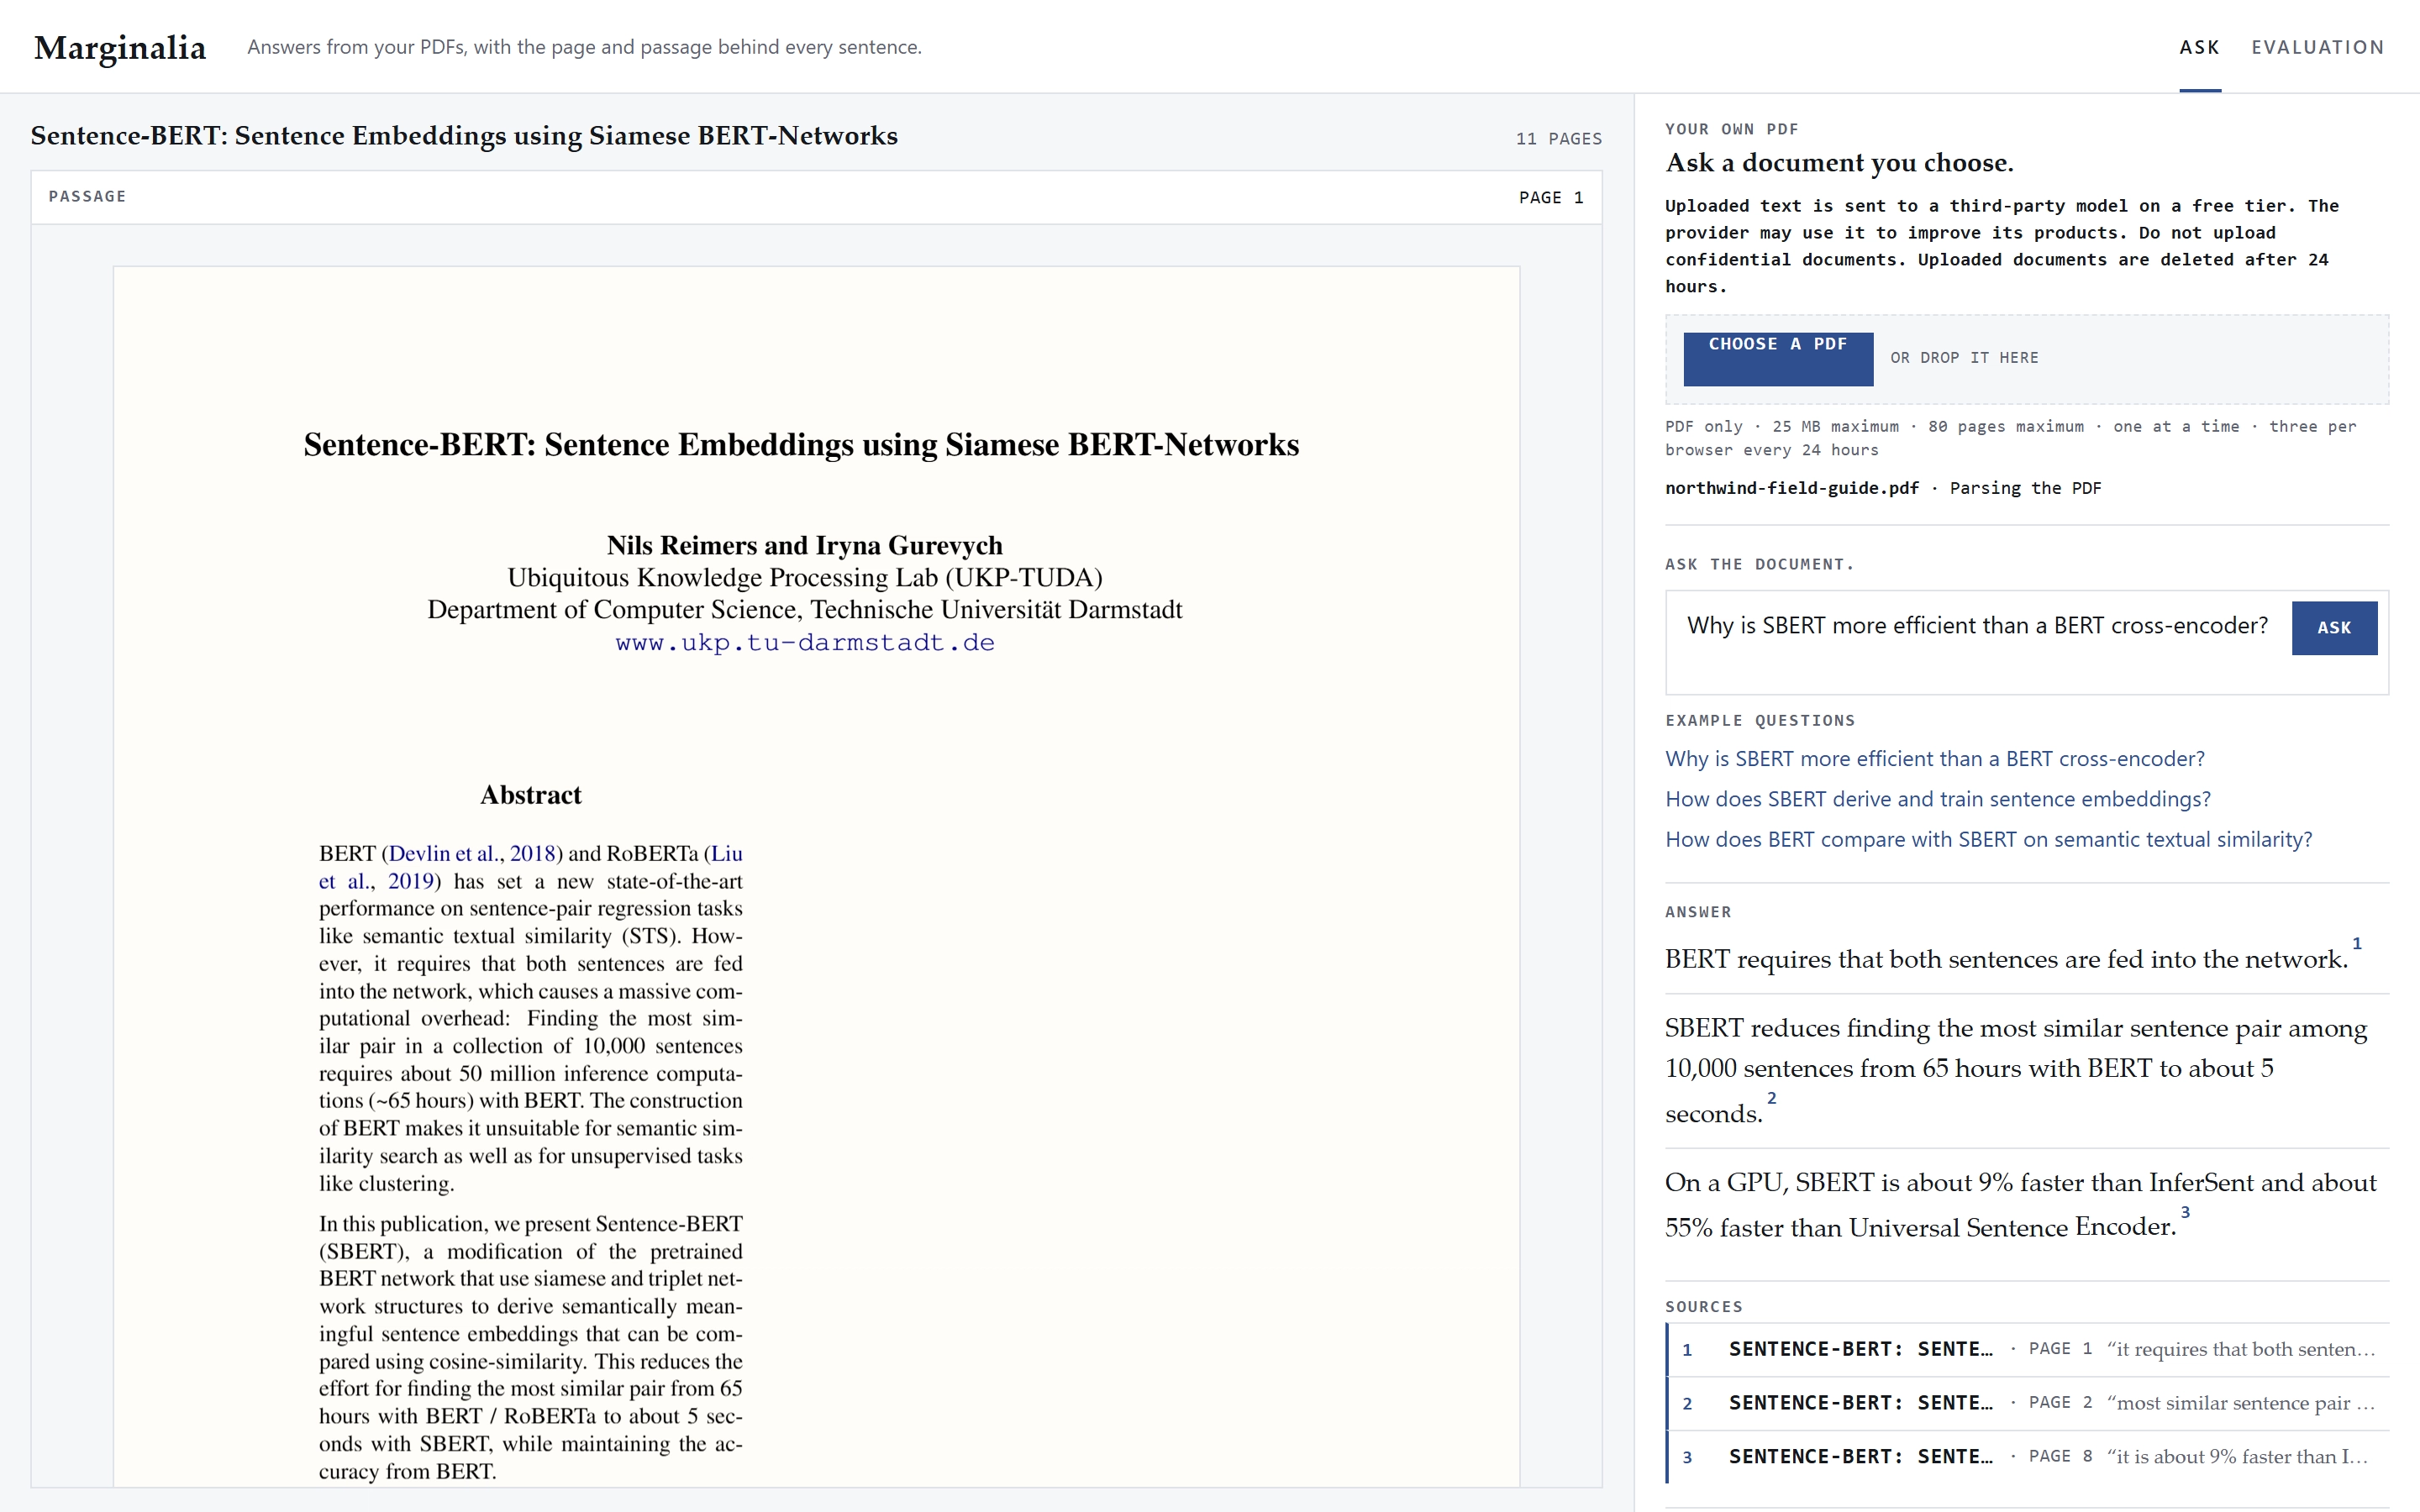
- A visitor upload is capped at 25 MB and 80 pages, sent to a third-party free-tier model, and deleted after 24 hours.
01 / What it is
What it is
A Python 3.12 FastAPI service with PostgreSQL 16 and pgvector, served with a React reader.
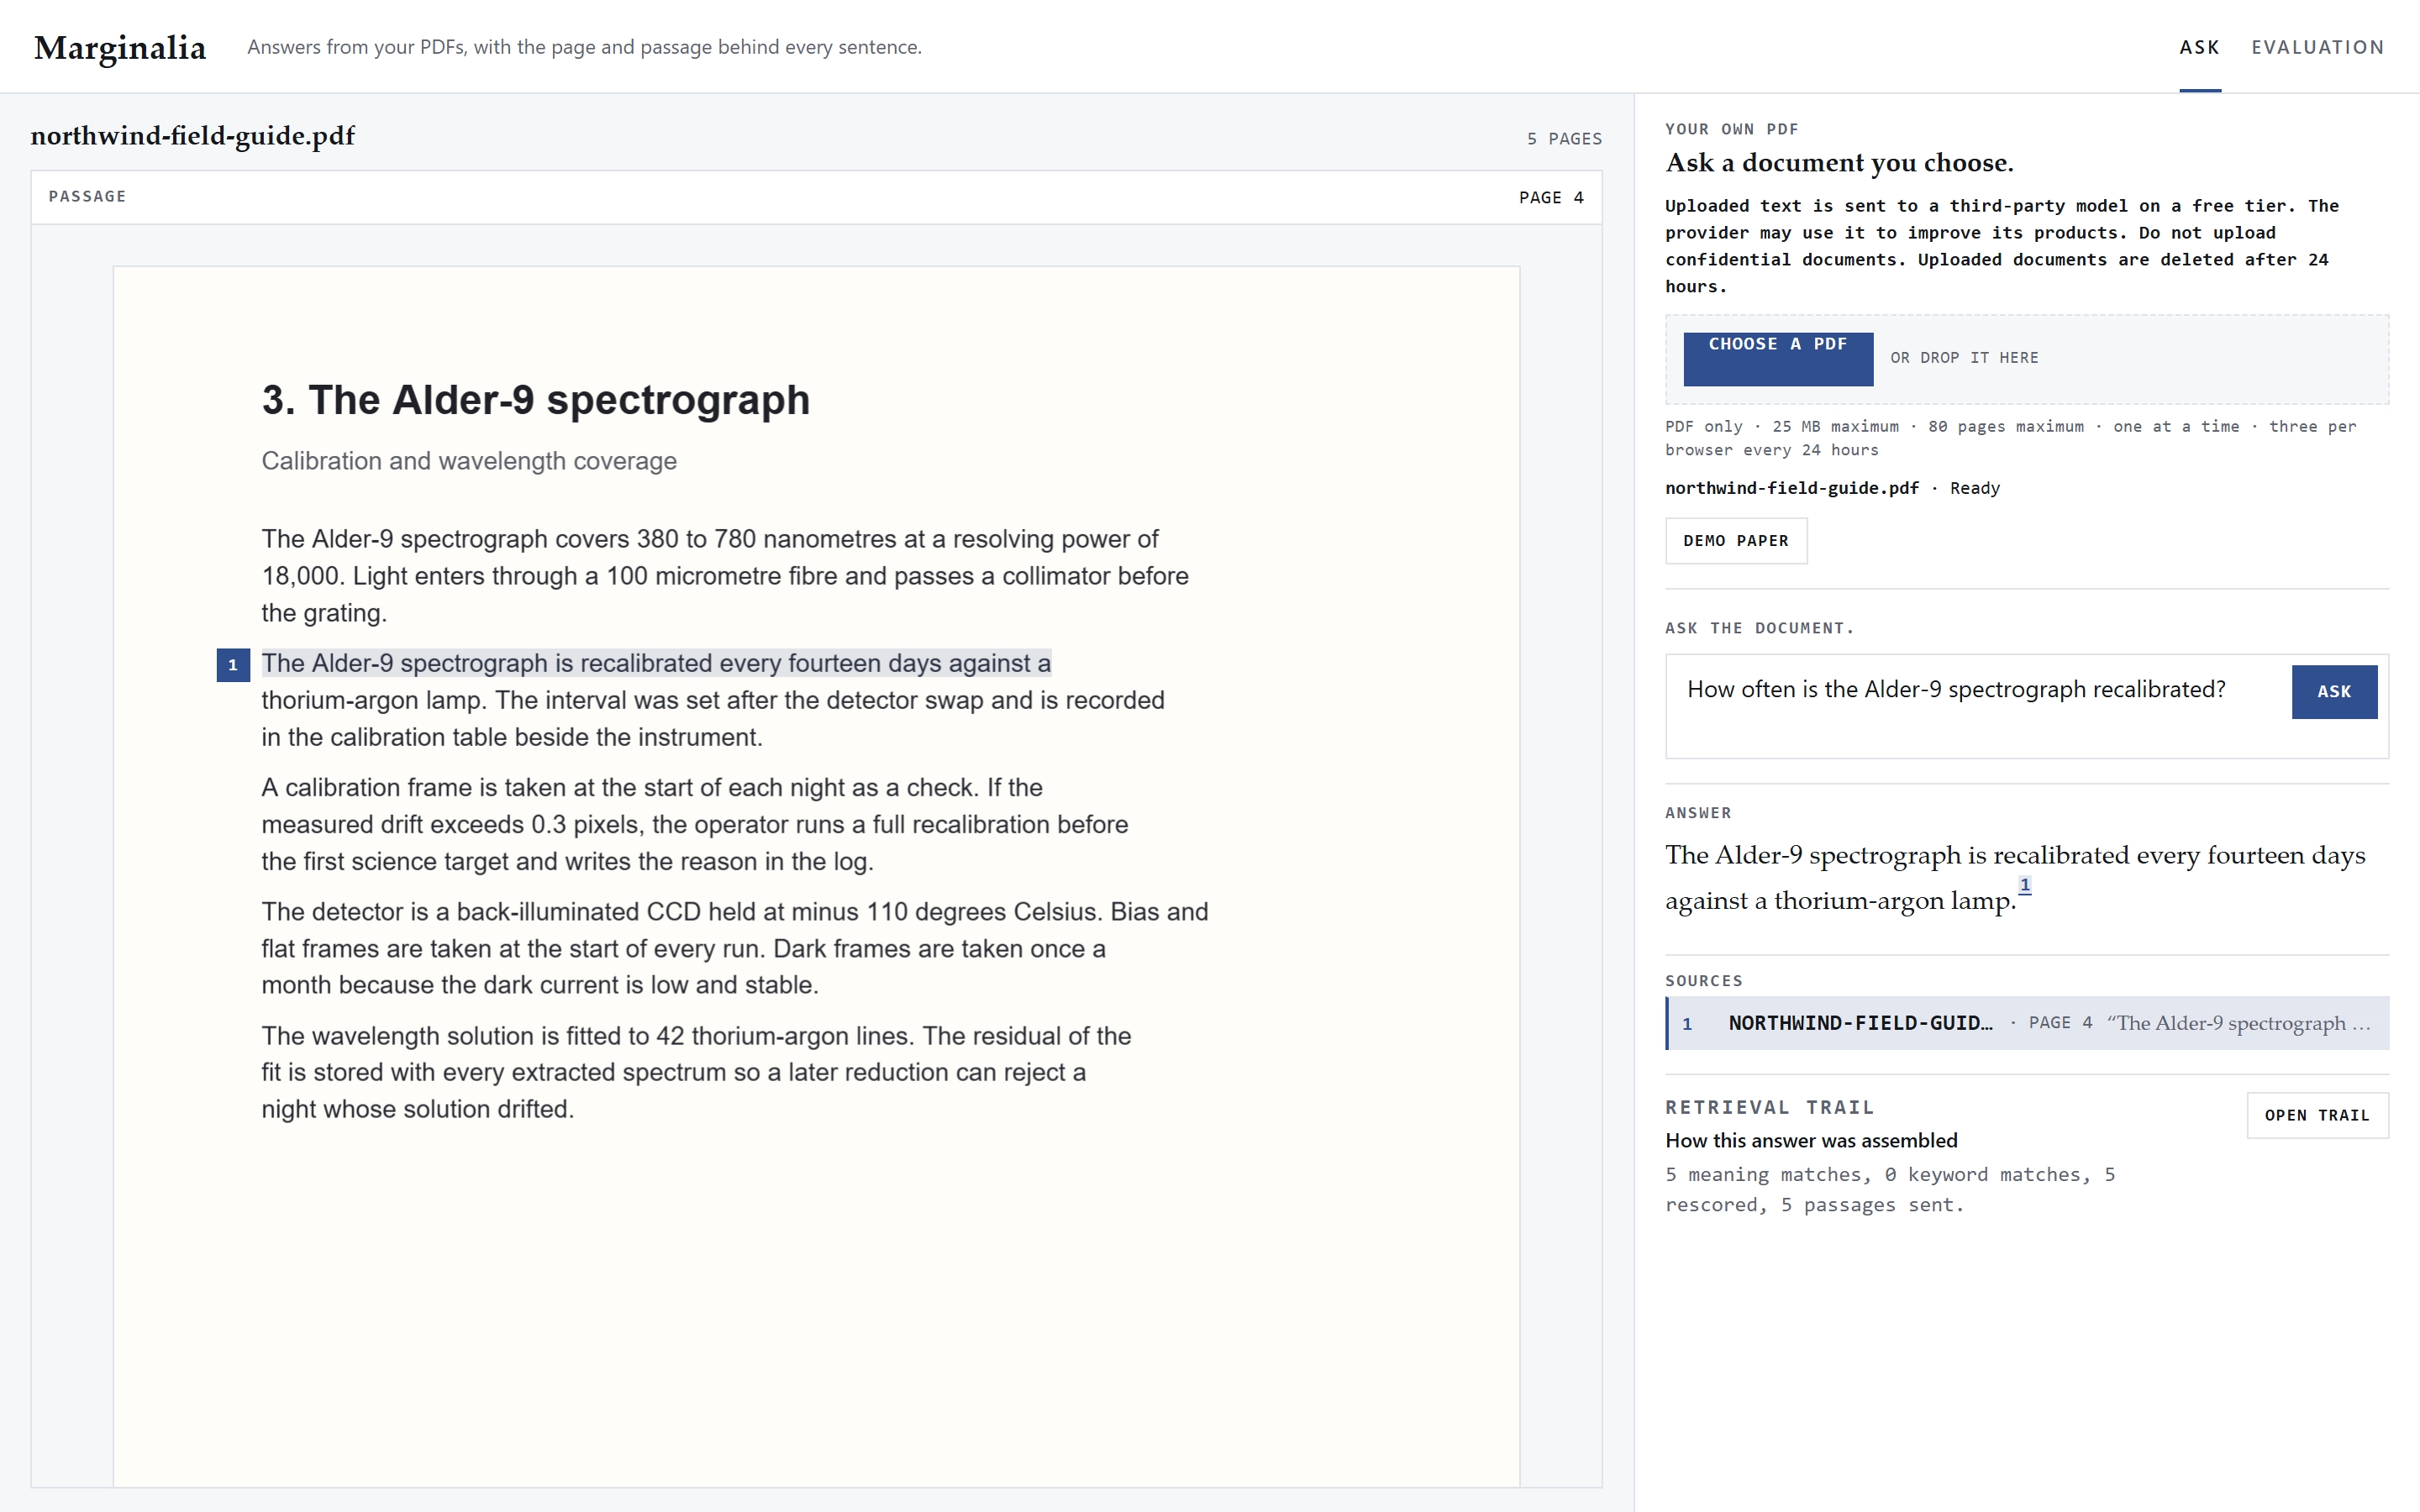
Ingest refuses a PDF whose SHA-256 differs from corpus.lock.json; retrieval fuses embeddings and lexical search, then reranks; the answer path keeps a claim when its quote appears in the cited chunk and drops it otherwise.
02 / The hard part
The hard part
A retrieval answer is easy to make plausible and hard to check. A claim can cite a passage outside the retrieved set, quote text outside the cited chunk, or survive a question the corpus holds no evidence for. The refusal path makes answers checkable.
03 / The decision
The decision
An uncited claim is dropped, not repaired
Decision Validate each claim against its citations, require a verbatim quote from the cited chunk, and drop it on either failure.
Rejected alternative Generate first, then attach the nearest passage; a citation added afterwards can miss the claim.
Cost The validator drops a reply whose quote is not a verbatim substring, so the answer rate is 15/24.
Evidence The citation tests cover the rejection path; the eval records answer rate and both citation rates.
04 / The failure it refuses
The failure it refuses
A fluent answer cites a passage outside the retrieved set, or quotes text outside the chunk it names.
Mechanism Every claim is validated against its citations: the passage must be in the retrieved context, and the quote a verbatim substring of that chunk. A claim that misses either check is dropped before the answer is returned; the refusal threshold is read from eval/calibration.json at boot.
05 / Measured
Measured
The keyed eval measured the five gates: recall@8 18/24, answer rate 15/24, refusal 6/6, citation precision 13/15 and faithfulness 12/15. The run took 710.3 s with 26 model requests, 0 retries and 0 rate limits. The hosted /ask answered in 27.5 s with a citation on page 8.
| Metric | Value | Method | Artifact |
|---|---|---|---|
| Retrieval recall@8, keyed production eval | 18/24 (75.0%), Wilson 95% [55.1%, 88.0%] | bash scripts/live.sh eval; generator gemini-flash-lite-latest, embedder bge-small-en-v1.5, reranker ms-marco-MiniLM-L-6-v2 on ONNX CPU | docs/EVAL.md |
| Answer rate, keyed production eval | 15/24 (62.5%), Wilson 95% [42.7%, 78.8%] | bash scripts/live.sh eval; generator gemini-flash-lite-latest on the keyed free tier | docs/EVAL.md |
| Unanswerable refusal, keyed production eval | 6/6 (100.0%), Wilson 95% [61.0%, 100.0%] | bash scripts/live.sh eval over 6 unanswerable questions; threshold read from eval/calibration.json | docs/EVAL.md |
| Citation precision and faithfulness, rule-based | 13/15 (86.7%) and 12/15 (80.0%), Wilson 95% [62.1%, 96.3%] and [54.8%, 93.0%] | bash scripts/live.sh eval; rule-based citation and quote checks, not a model judge | docs/EVAL.md |
| Production eval run cost | 710.3 s · 30 questions · 26 model requests · 0 retries · 0 rate limits | bash scripts/live.sh eval; provenance.run in eval-report.json | docs/ENV.md |
| Hosted /ask contract | HTTP 200 · 27.5 s · chunk 128 · page 8 | curl -X POST https://marginalia-api-4pvl.onrender.com/ask with the SBERT question; transcript in docs/PROOF.md | src/docqa/api.py |
Invariants and their tests
- Ingest refuses a chunk longer than 448 model tokens rather than storing a truncated vector.
tests/test_chunking.py - A claim without an in-context citation, or whose quote is not a normalised substring of the cited chunk, is dropped.
tests/test_citations.py - The refusal threshold comes from eval/calibration.json at boot and is never hand-tuned.
tests/test_refusal.py - Every rate carries a Wilson 95% interval and its denominator; the eval records the earliest stage that produced no answer for each question.
tests/test_eval.py - The judge model differs from the generator and is pinned by exact id; its reliability is recorded by the judge check.
tests/test_judge_check.py - ONNX work runs in a worker thread behind Semaphore(2).
tests/test_embedder.py